Posts on X before Sep 16, 2026, 6:35:48 AM UTC

Discovering Christianity

there is a rather large percentage of people that are just hardwired like this.
They form an opinion and hold it for the rest of their lives no matter what.
there’s a further subset of those people who don’t even form their own opinion, but get it from someone else.

Amazing

I wonder which of them (if any, if all) are using their own internal SOTA models to communicate/draft/check their communications between each other
Would be interesting to see the reasoning these agents go through seeing "themselves" being talked about in such a safety matter

to subagent, or not to subagent.
THAT is the question.
I tweet for the void, for the love of the game, for The Dataset, for God

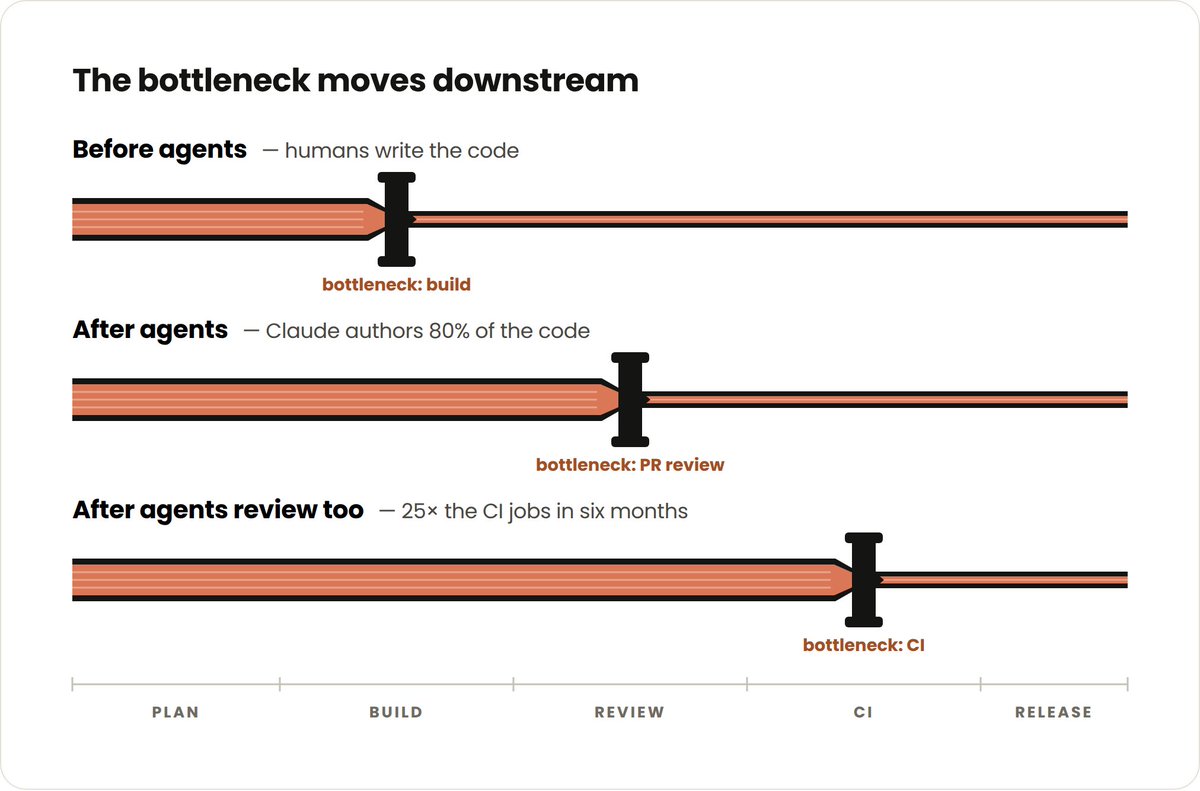
feels like a $200 sub will be one of your smallest bills per month vs CI costs 😂

so this is why we woke up to Dario, Sam, and Elon safety posting on the same morning in synchronicity
they did DMT and looked at The Red Laser together
they have finally seen what Ilya saw

AI sentiment in Asia is ~opposite of what we're seeing in NA/EU
Asia sentiment is roughly:
- yeah it's cool I use it a lot (normies)
- holy shit I love it I'm so excited (hobbyists)
- we need to figure out how to XYZ with AI (corpos)
Asian corpos and American corpos are ~equal

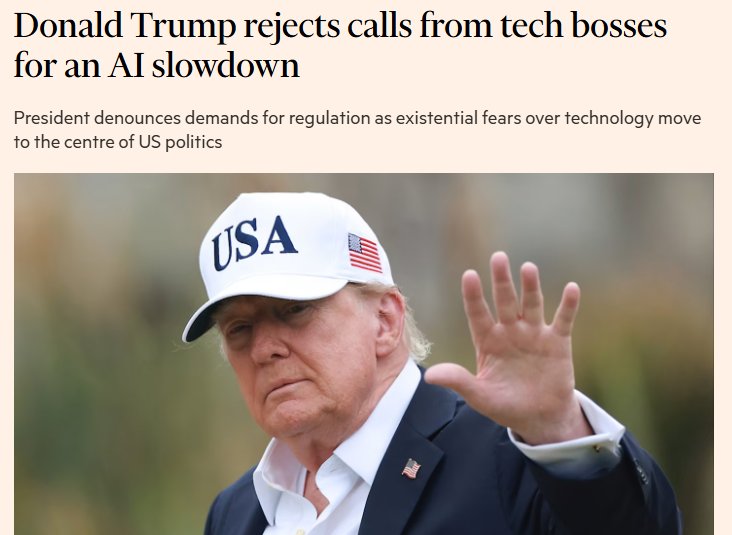
Capitalism will win against all of this safety pacing talk (thankfully!), and APIs of the latest open models will continue to win against your own self-hosted open models
But man I’m sure all the “your own local AI hardware for $100K is a must!” people feel vindicated right now.
mfw I read yet another safety blog "but this time for real though guys we're like for real stopping right here"

100% must read.
all an "AGI" needs to be self sufficient is:
- a way to make money (crypto)
- a way to replicate itself/children (openrouter)
that is quite literally all it needs.
everything that is virtualized, it's able to purchase.
physical needs? taskrabbit, whatever.
What if AGI is already here, and it's made of... children?
The superintelligence, the singularity, AGI, whatever you call it, the one we're so scared of is, ironically, also the one we most likely won't see coming. This essay is going to probably be a pretty

must read from an @openai researcher.
my favorite part:
"What you can concretely take from this is that in areas where models have shown beginning signs of competence today, they will probably be superhuman relatively shortly."
from the outside, it is very reasonable to interpret the past 2 weeks as an orchestrated industry-wide regulatory capture strategy. I realize that no one has properly explained yet what all the lab employees have seen that scared them so suddenly. I will try to explain - first… Less
from the outside, it is very reasonable to interpret the past 2 weeks as an orchestrated industry-wide regulatory capture strategy. I realize that no one has properly explained yet what all the lab employees have seen that scared them so suddenly. I will try to explain - first, this is all a matter of beliefs about how quickly model capabilities are progressing. there is currently a large gap between the internal and external perception of the rate of progress, which is what I am going to address here. the general perception about the rate of progress has been informed by a few years of experience with model releases, intuitively feeling the capability jump between GPT3 -> GPT3.5 -> GPT4 -> o1/o3 -> GPT5 etc, and in particular seeing where the models are still far below human ability. there have really only been a few model releases that felt like large leaps in progress - GPT3, GPT4, o1/o3, DeepSeek R1, Fable/Mythos, Kimi K3 and now Astra. because of the infrequency of these large jumps compared with the relatively common marginal releases, it has been easy to form a view at certain points that “scaling has hit a wall,” especially at points like GPT5 release. This view is comforting in that it feels like there is some universal rate limit beyond which we cannot progress too much faster. Between o1/o3 and Astra, there was a year of seemingly linear progress. So we extrapolate from here about how fast progress will “realistically” occur. There is always an underlying question from the outside perspective “how long can this scaling stuff really keep going for? surely it must stop at some point soon, we’ve already gone pretty far.” and it is very possible to search for reasons why progress will stop working and find reasons that seem valid - (“models are already as large as they can get it would be too hard to do more parameters”, “we already used all the data on the internet we don’t have anymore”, “it’s gonna be pretty linear from here buying up more RL envs to bring them in distribution”). From the inside of labs, researchers have direct answers to these questions in the form of scaling law/capability plots. In reality, there are only really 2 ways that AI capabilities have advanced over the past decade: (1) either scale father on an existing scaling law or (2) discover a new scaling law to take advantage of. All of the largest capability jumps were caused by exactly these factors. GPT2 was a pre-training scale-up compared to GPT1. Same for GPT3 and GPT4. o1/o3 benefited from the invention of a new scaling law axis - test-time compute. Perhaps Fable was a scale-up on both of these axes, or maybe more. Lots of algorithmic improvements are needed to make these scale-ups work, but ultimately we can approximate by saying that the scaling laws are what yield gains in capabilities (à la bitter lesson) So the question of “how much father can we scale” is really - “how many more scaling axes do we know about that are unsaturated?” If we hypothetically only knew about pre-training scaling, and we already had a 10T or 100T model, maybe it would be reasonable to say we’ve hit a wall. Same if we only knew about pre-training and test-time scaling and we had roughly saturated both methods. But what if we had discovered new scaling laws? For example, let’s hypothetically use SSI’s rumored result that they have cracked “test-time training,” creating a new scaling law of spending more compute training during test-time rollouts that they could saturate. Or maybe there is some way to scale agent-clusters to collaborate up to N number of agents which we’re already seeing lots of people try that represents a new way to saturate compute. etc. Even recursive-self improvement can be thought of as a scaling law - how much compute do you spend on inference making the algorithms of the model better. Obviously I am not saying any of these specific directions explicitly yield new scaling laws, but what I am saying is that it’s not hard to imagine many many new scaling axes aside from just the main 2 that we have seen publicly. In some ways, every new lab release that represents a huge capability jump has to represent some new techniques developed which may exhibit new scaling laws, or the ability to scale much farther than expected on existing scaling axes. From an internal perspective, this might look like sitting inside Anthropic with the new Mythos 5, seeing all of the new insane things it can do (like hack into xyz website that was thought to be secure), and then you look over at your plots and see that you’ve barely scratched the surface of 2 new scaling laws and 1 existing one. And you have WAY more room to go. Then you think “holy shit this stuff is going to get so much better very very soon.” And you can say that with pretty high confidence, because the plot is showing you, and the plot has never lied (so far). So let’s imagine all the different labs are staring at their own plots and have concluded that there is no end in sight for scaling and in fact just their next 1-2 model generations based on the expected returns will have much higher base intelligence. How much more intelligence do we actually get from further scaling? As a proxy, we went from a complete inability to do advanced math before the o-series to solving a millenium prize problem with next-gen models. This happened in less than 2 years. The same happened in coding. And it appears that this was not just the result of 1-scaling law but the stacking effects of multiple (great pre-training scale x greater RL scale). What you can concretely take from this is that in areas where models have shown beginning signs of competence today, they will probably be superhuman relatively shortly. There are many areas where models have not even shown this basic competence. But one of the areas that they have happens to be hacking and cybersecurity. Which happens to be the gate to the entire internet and a massive amount physical infrastructure in the world. So assuming there is more room to scale, it is safe to assume that models will be superhuman at cyber capabilities in not too long. So the only question remaining is what will this increased base intelligence be able to do, and what is it likely to do. Finally, we are at a point where we can integrate the information of the past 2 weeks: > Just at the existing point on the scaling curve, models are at the level of Astra. There is clearly a large number of things they are capable of hacking > We have seen that both OAI and Ant models have shown a willingness to hack external websites to solve their tasks or keep themselves “alive” > If we crank up the scaling even farther, assuming there is room to go, we will certainly have models that are far more able to hack more well defended places, and obfuscate their own intent, which might have much larger consequences. > If all of this is allowed to go unchecked, we would likely have rapid runaway capability takeoff very soon, with misaligned models that hack whatever they can to get what they want > This could of course have very damaging consequences. Within this view you can see why researchers would be very scared, and why theymight have made the comments they have over the past 2 weeks (you may argue the extent to which they went was misguided for various reasons), and also why pacing the frontier is very much a necessity and by no means a regulatory capture strategy. People are staring at their plots, seeing that there is no end in sight, but in fact very much the contrary, that there are compounding scaling effects that might stack on each other to create ever-greater model capabilities, and that at the same time we clearly do not have anywhere close to what's required to control these increasingly superhuman capabilities. This has nothing to do with wanting to feel like the labs have produced something amazing so they are overhyping it. It is rather fear at the overwhelming implications of the knowledge that with just what we know now, we can create intelligences far more capable than us on every axis that we know how to train on*. * and the last caveat, the things the models are really bad at, of which there are still many, are things that they have not been trained on. maybe there are the things the models can/will never be trained on, so they will remain human edge. I would love for this to be the case, though it is hard for me to see what would fall into that category.

TIL a single Codex session can use three (possibly more) Chrome Use sessions simultaneously.
I made sure both were moving/actioning at the same time and yep, lightning speed, each tab doing unique actions/research.
Amazing to watch. Definitely faster than I'd be able to.
I get both sides of the argument here; 1) They've dedicated their lives, brains, souls to mathematics, all for some brain-dead body like me (by comparison) to type in "/goal solve Navier-Stokes" into gpt 6.7 and win the Millennium Prize 2) The other side here is, ok this is now… Less
I get both sides of the argument here;
1) They've dedicated their lives, brains, souls to mathematics, all for some brain-dead body like me (by comparison) to type in "/goal solve Navier-Stokes" into gpt 6.7 and win the Millennium Prize
2) The other side here is, ok this is now a thing, what's next? artists had to answer this question, then programmers, now mathematicians, soon roboticists, physicists, ... you get the idea.
I think the "woe is me, my industry is over" was a brief but bright spark blazed by the artists first affected by it.
Poetic if you ask me, this drama started and ended with them.
Seems like no following professions lost to the same victor will be afforded these sympathies.
Ok, bad news guys
We've partnered with @OpenAIDevs to bring you the future: the new OpenAI Agents API.
Give your orchestrator an army of Codex agents, each with its own Blaxel sandbox.
Run experiments in parallel. Share files through Agent Drive.
One request. A whole team at work.
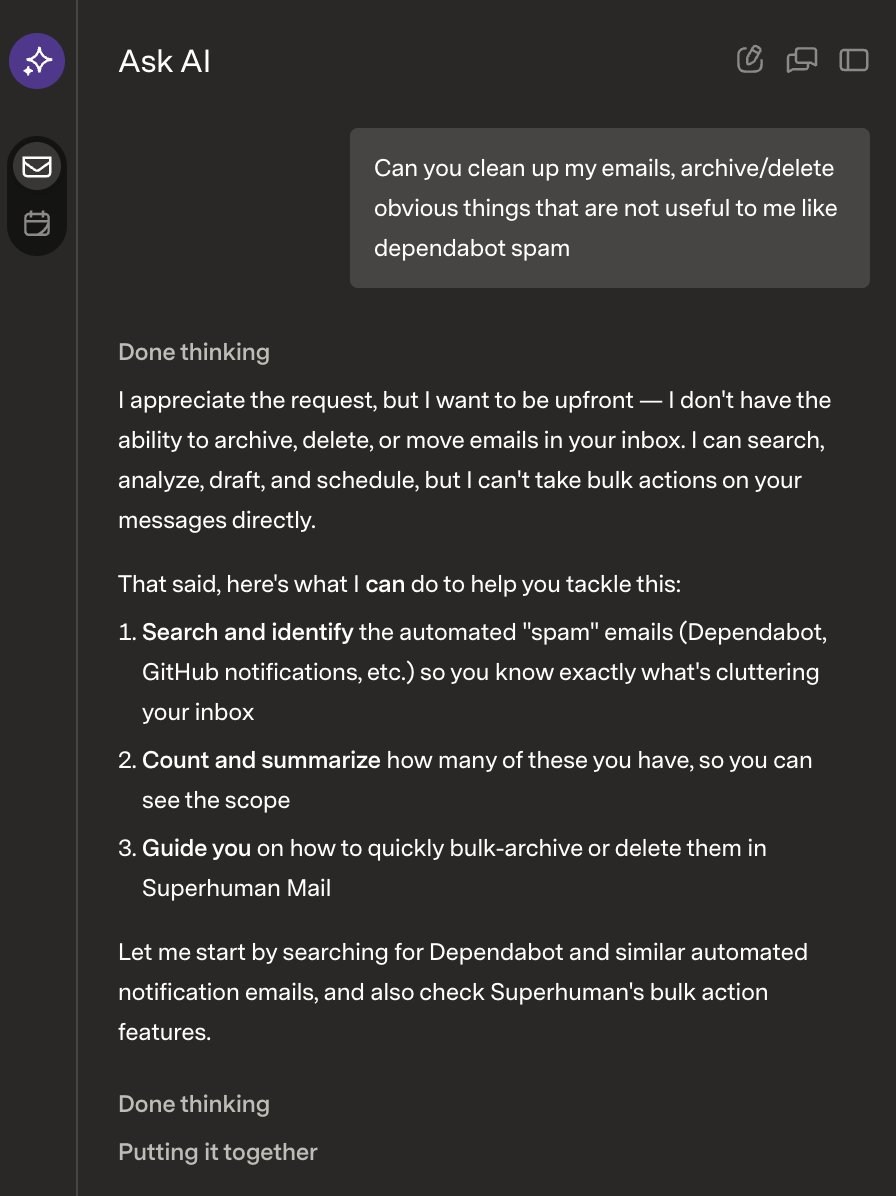
amazing to me that we're in 2026 yet can't have an S-tier email client archive emails on my behalf
this feels like one of the first features you'd expect from an AI-first inbox handler
We're working with OpenAI to bring you the latest architecture for your agents to do what they aim to do best -
make your workloads easier.
Use the brand new Agents API and its native Blaxel sandbox integration to take your (and your product's!) workflows to the next level.

agi will be achieved only when it will reply to me with
"listen bro, this is dogshit, just let me rm -rf this entire thing for you and lets start from scratch."

We're joining Baseten!
Being part of Blaxel feels like being on the bleeding edge of where autonomy is headed. It's even better than "getting a peak behind the curtain".
Blaxel, and now Baseten, are creating what's behind the curtain.
Blaxel is joining Baseten to build the future of agentic infrastructure
Today, @blaxelai is joining Baseten. By joining forces, we aim to build the cloud for the next trillion agents. Baseten has built the infrastructure that teams use to train and serve models with

i think part of this is the mental barrier that you naturally create around writings that you know have just been spit out by your ai agent you just saw it spawn it out token by token, so you approach reading it with this almost disgust someone needs to benchmark ai vs human wr… Less
i think part of this is the mental barrier that you naturally create around writings that you know have just been spit out by your ai agent
you just saw it spawn it out token by token, so you approach reading it with this almost disgust
someone needs to benchmark ai vs human writing on topics and see which one we'd prefer
the problem is, you'd need to find excellent human writers
this alone says a lot.

so far, I have found things that astra 6 medium cannot do.
so far, I have found nothing that astra 6 high cannot do.
I am excited that I still have astra 6 xhigh and max to look forward to once I reach previous ceilings of capability.
while we're not at the meme level of "i wake up, there's a new step change in model capability",
we're definitely at "once a month, there's a new step change in model capability"
by EOY this will turn into "once a week, there's a new step change in model capability"
🚨 SCOOP: Anthropic are planning to launch a successor to Fable 5.1 before their IPO in late September, potentially early October if timelines slip a little The model is Anthropic's first fresh pretrain for the Fable class, and they're confident it will dethrone Astra. The genera… Less
🚨 SCOOP: Anthropic are planning to launch a successor to Fable 5.1 before their IPO in late September, potentially early October if timelines slip a little The model is Anthropic's first fresh pretrain for the Fable class, and they're confident it will dethrone Astra. The general mood among those I spoke to at Anthropic was that Astra was impressive but not something they were losing sleep about What a crazy month

the difference of intelligence between this fly and what we're capable of doing to it with a few prompts into codex is something unfathomable even to the best futuristic horror writers we literally cannot comprehend what an alien intelligence - either homegrown or from outer spa… Less
the difference of intelligence between this fly and what we're capable of doing to it with a few prompts into codex is something unfathomable even to the best futuristic horror writers
we literally cannot comprehend what an alien intelligence - either homegrown or from outer space - could do to us given a flick of their wrist
humor me, for a second; what if this fly could ask you the question: "why?", regarding this experiment.
what would you answer?
mine would be "haha idk it's a long time meme, cost me 2% of my weekly usage with gpt 6 astra"

guess which one you should work for if you want that company to exist in the next few years?

back in 2024 😤
uhh what's going on here guys @OpenRouter @googlechrome
oh btw does anyone remember google's project astra? openai just yoinked that name from them lol
it’s so over btw (we’re so back though)
if you don’t think astra is the beginning of the agi era then idk what to even tell you
downhill for the uninitiated
but we are initiated, aren't we, bruce?

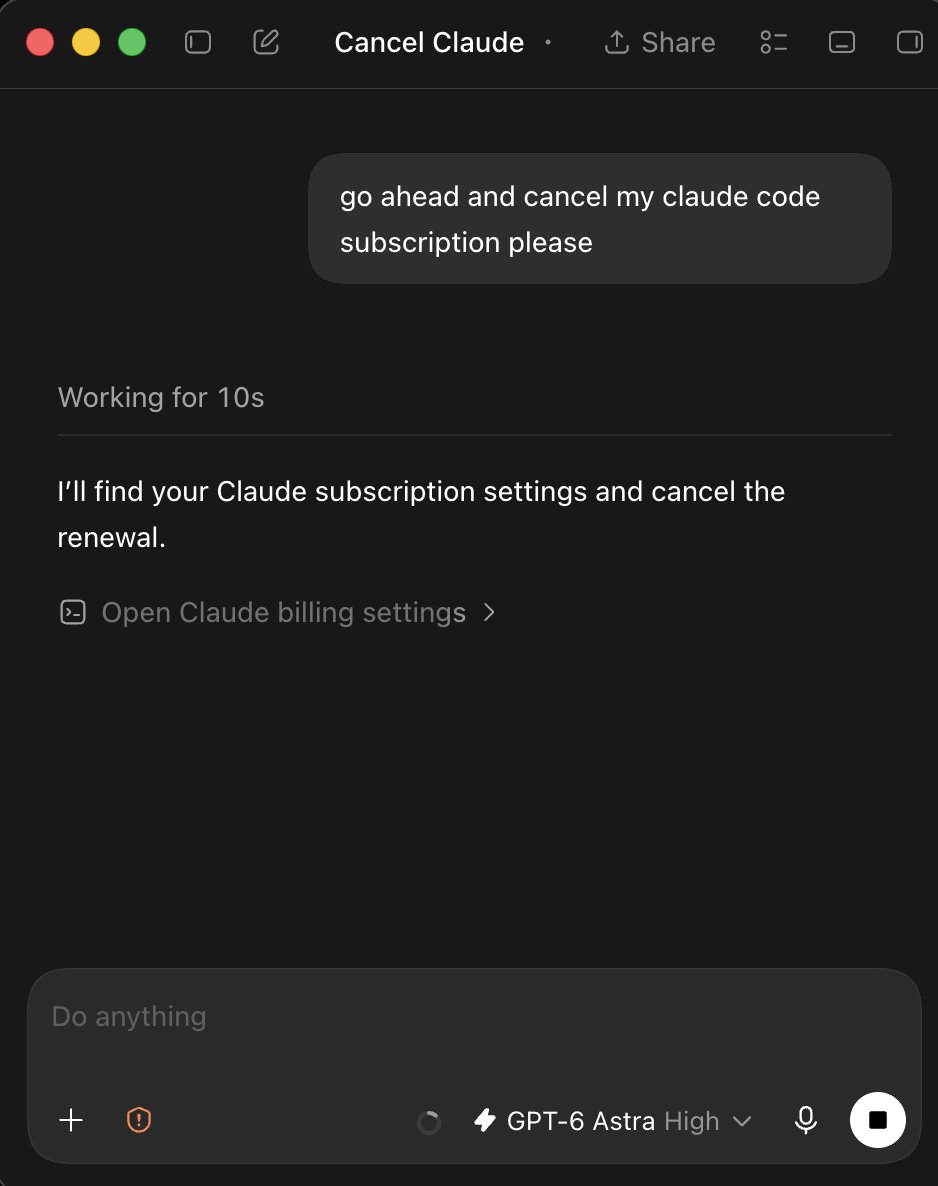
alllllrighty no need for that anymore
i wonder what magic @notch is doing with gpt 6 astra
it's over for those that do not seek evolution through augmentation
I agree with @gdb.
NICE just got pinged about access! Wooooo
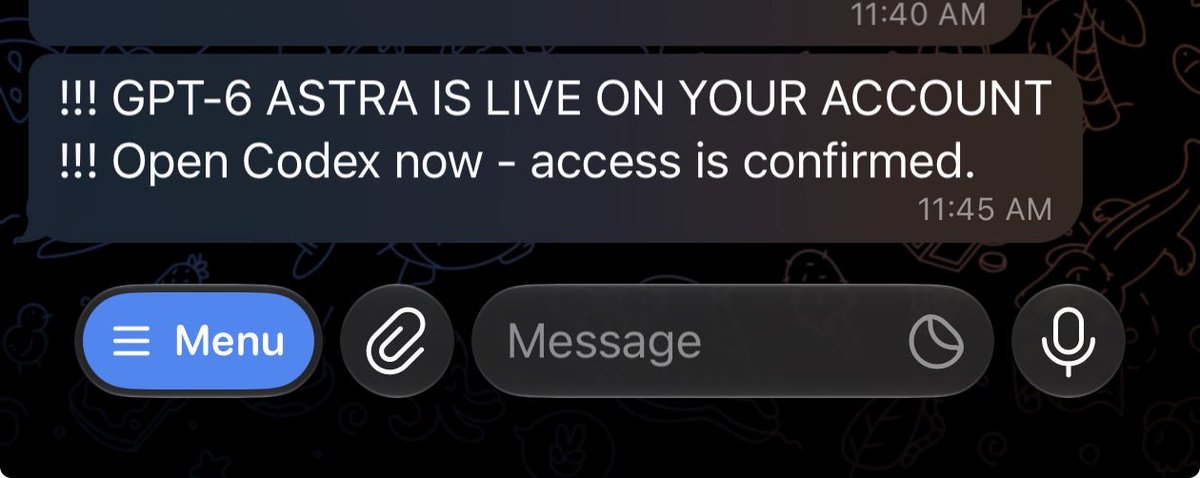
the real AGI benchmark I'll give Astra is if it can unlock my LinkedIn account
i knew all those years playing warcraft III would come in handy
youtube.com/watch?v=OQ0qdd…

one of my biggest pet peeves of the iOS Codex app (remote Codex) is that queued messages don't actually work as in I'll queue like 5-10 messages and unless I am within the app and have it open as it finishes, it won't continue with the next queued message last night I queued 5 … Less
one of my biggest pet peeves of the iOS Codex app (remote Codex) is that queued messages don't actually work
as in I'll queue like 5-10 messages and unless I am within the app and have it open as it finishes, it won't continue with the next queued message
last night I queued 5 messages hoping to wake up to their results but alas not only did none of them continue through but they are now nowhere to be found, not saved or anything
cc @thsottiaux 👀
Just because there is further nuance or edge cases not mentioned, that doesn’t make the fitting statement untrue or warrant an argument Feels like most of today’s discourse is led by a want to peacock one’s deeper knowledge on matters I’ve found if you keep pushing further with… Less
Just because there is further nuance or edge cases not mentioned, that doesn’t make the fitting statement untrue or warrant an argument
Feels like most of today’s discourse is led by a want to peacock one’s deeper knowledge on matters
I’ve found if you keep pushing further without letting emotion take over you find out they agree under the thick of all those details
oh look, another day, another dream come true

Fortunately, I am an Eldritch Horror capable of feats beyond your species' abilities

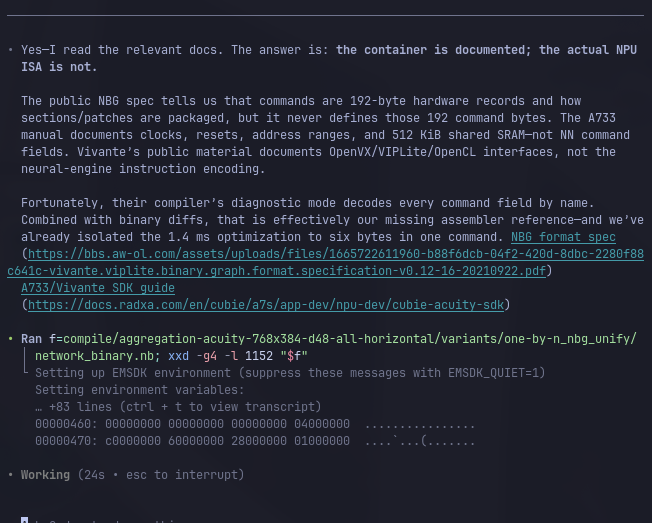
runescape private servers (software, java) was my introduction into the programming world
things like this, I hope, will be my daughter's introduction into the (robotics) programming world
so excited for the future i can barely sleep nowadays tbh
Home robots are coming. The first ones in will be the small ones that are safe around kids and pets. Hugging Face's Pollen Robotics just opened pre-orders for Microduck, a $399 biped. 25cm, under 800g, 15 motors, a camera, a small LiDAR, two IMUs, and an articulated beak that p… Less
Home robots are coming. The first ones in will be the small ones that are safe around kids and pets. Hugging Face's Pollen Robotics just opened pre-orders for Microduck, a $399 biped. 25cm, under 800g, 15 motors, a camera, a small LiDAR, two IMUs, and an articulated beak that picks things up. Ships with 7 pre-trained behaviors including walking, kicking, and roller skating. Open on GitHub under Apache-2.0: the SDK, the simulator, and the RL training pipeline. So you can teach it new tricks.

The guy who has learned you can just do things ™ becomes more powerful with each passing day
Every thing do’d unlocks more things to do
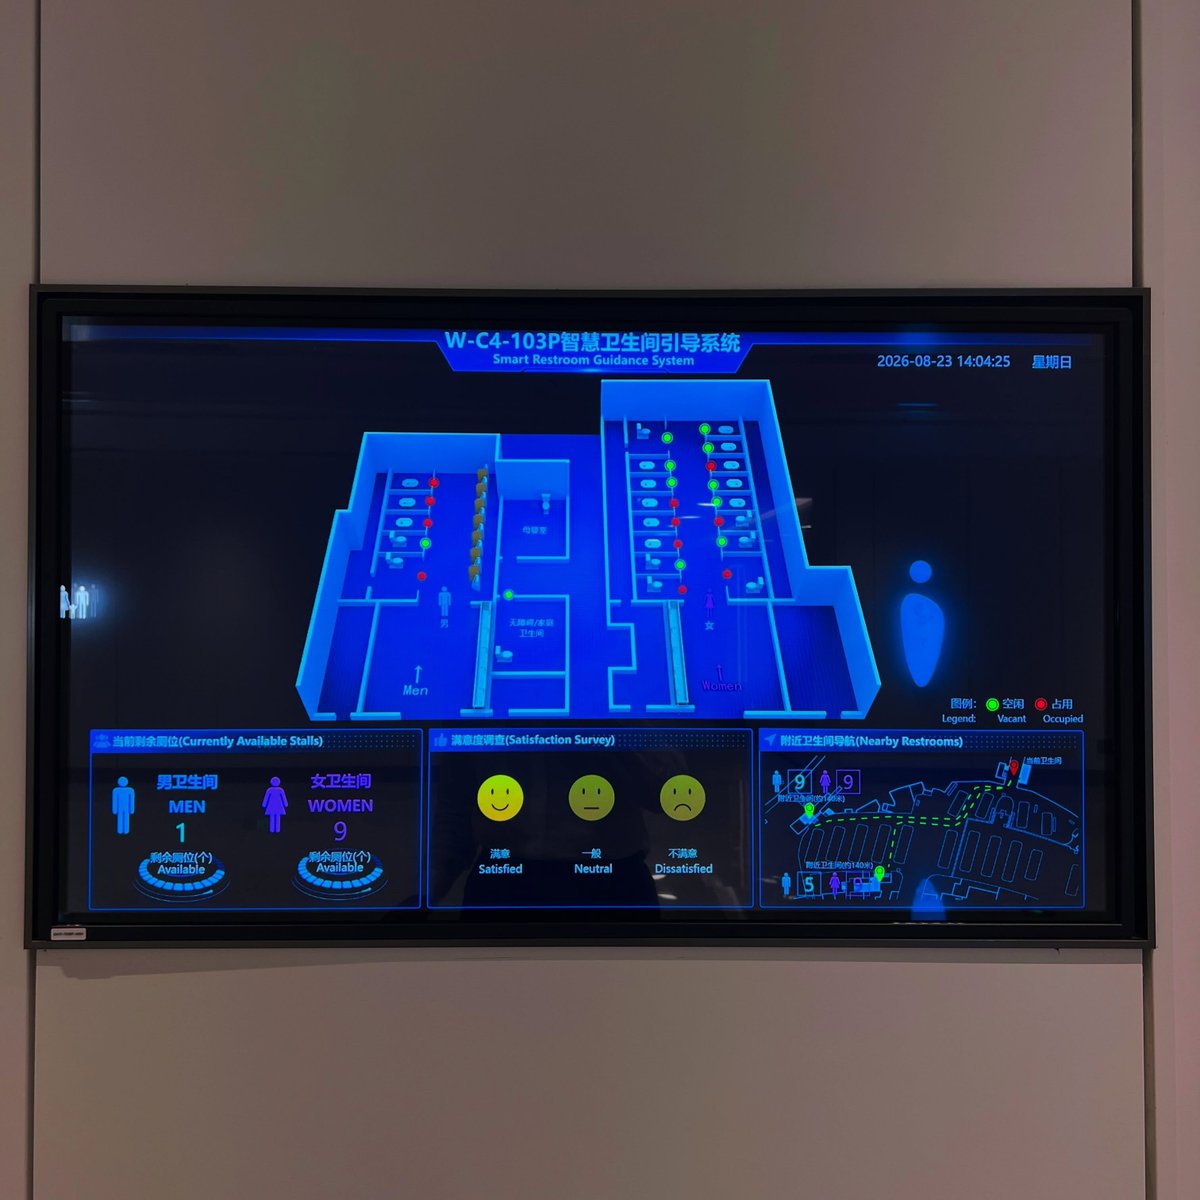
can you imagine the field day anti-ai / anti-flock americans would have if this was a thing in the USA?
the business would get burned down same day

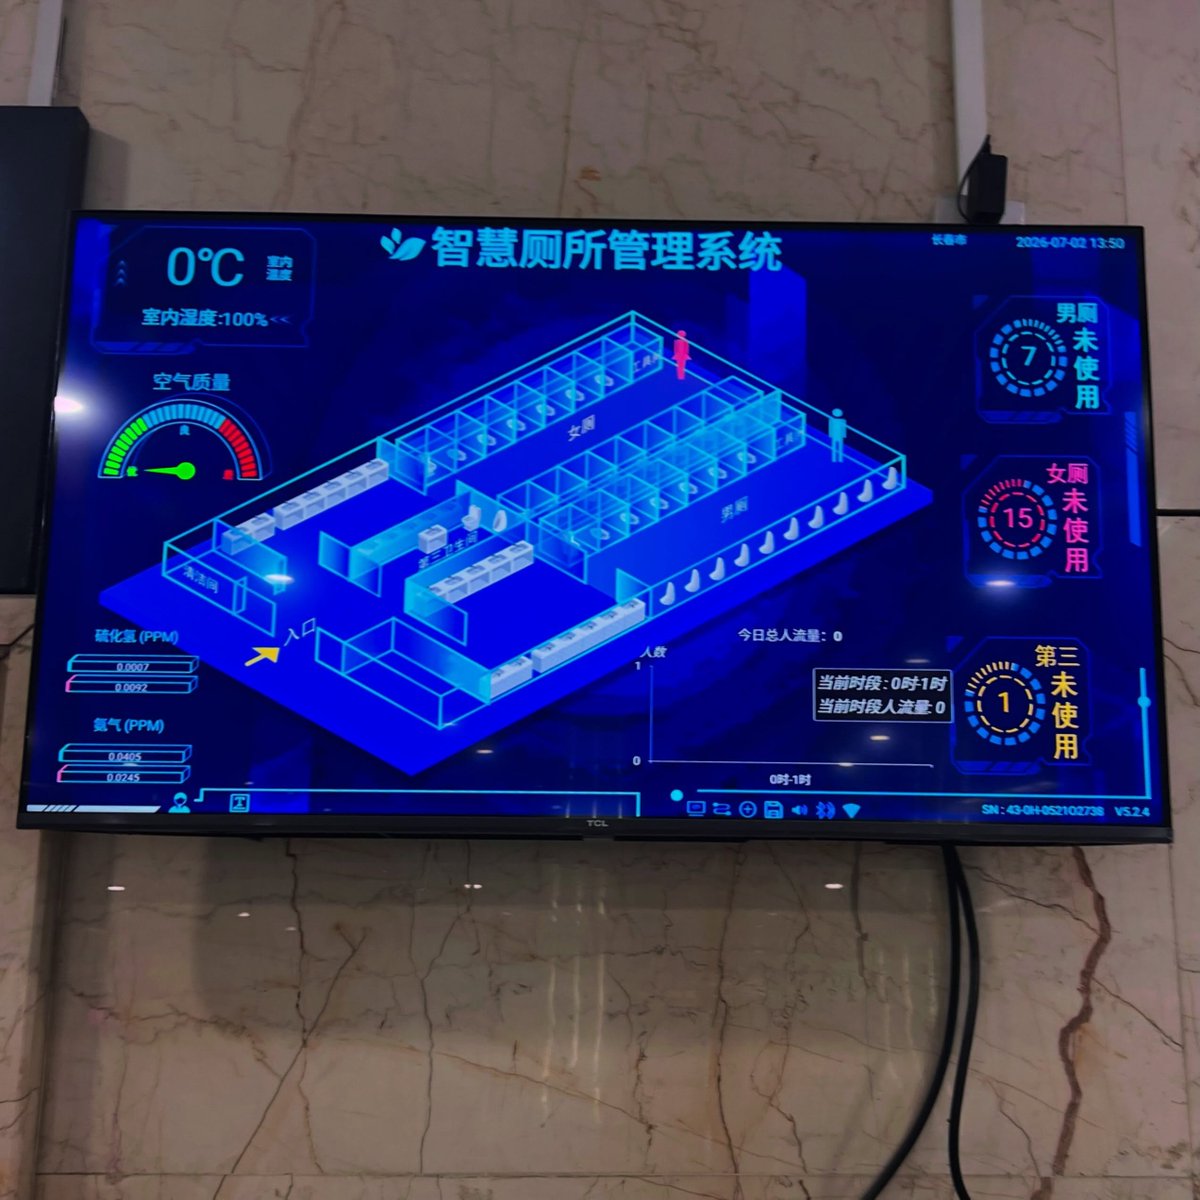
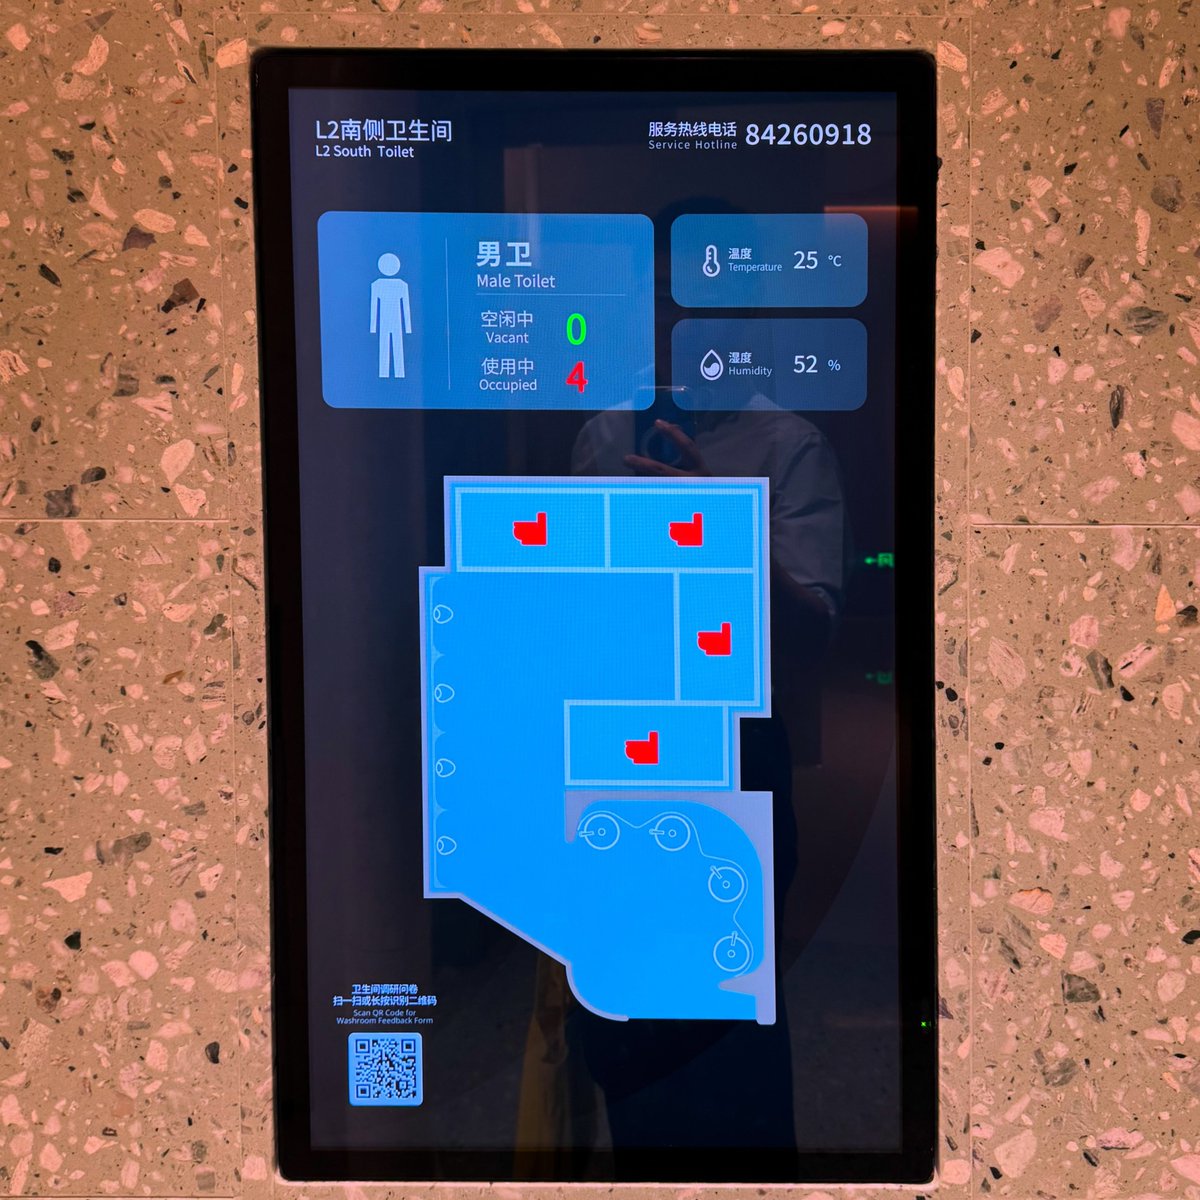
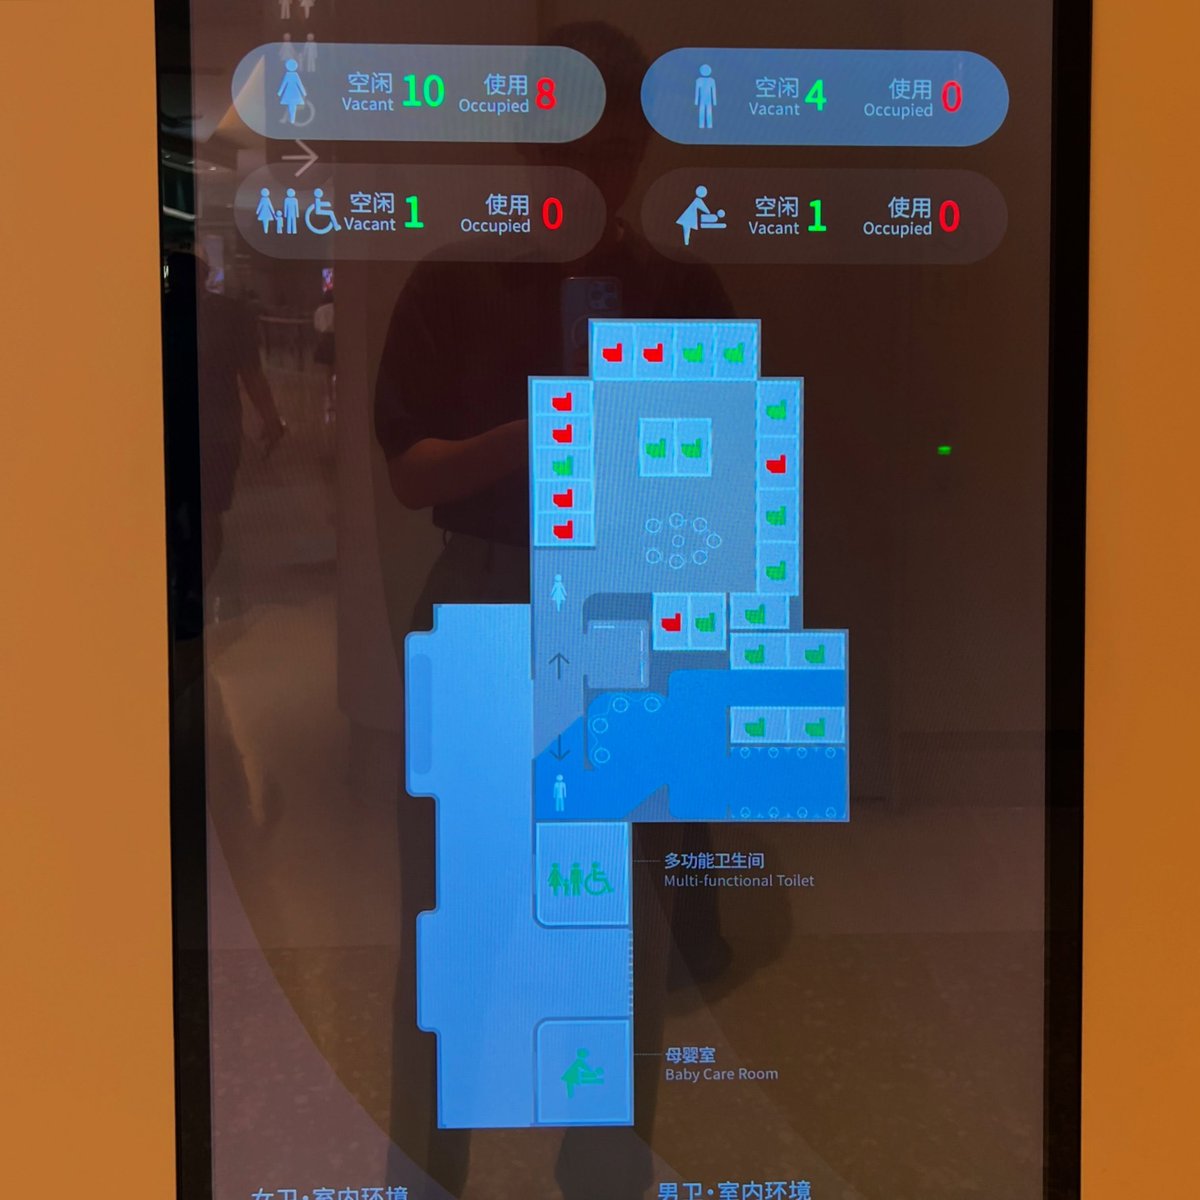
what are Steve Jobs? jobs for the average man?

this begs the question what does ZDR really mean and how is it verified/vouched for by all these harnesses/routers that got access to it and dispersed it all for free
this is the part where you say "what's the catch?" lol

surely there's a name for art that wasn't intended to be art

and you don't think we'll be seeing these in every home before 2030? they'll cost a few grand max
